A brake is not a heading
A researcher leaves Anthropic saying no one is acting responsibly, and the public response is to decide who brakes: a law, a regulator, a kill switch. But most people don’t sign laws or train models: they coordinate projects, maintain systems and write with these tools. For that majority the question isn’t who’s in charge, but whether what they use lets itself be governed. Three measured cases, in project governance, infrastructure and authoring, and what ontoref decided to do with each one.
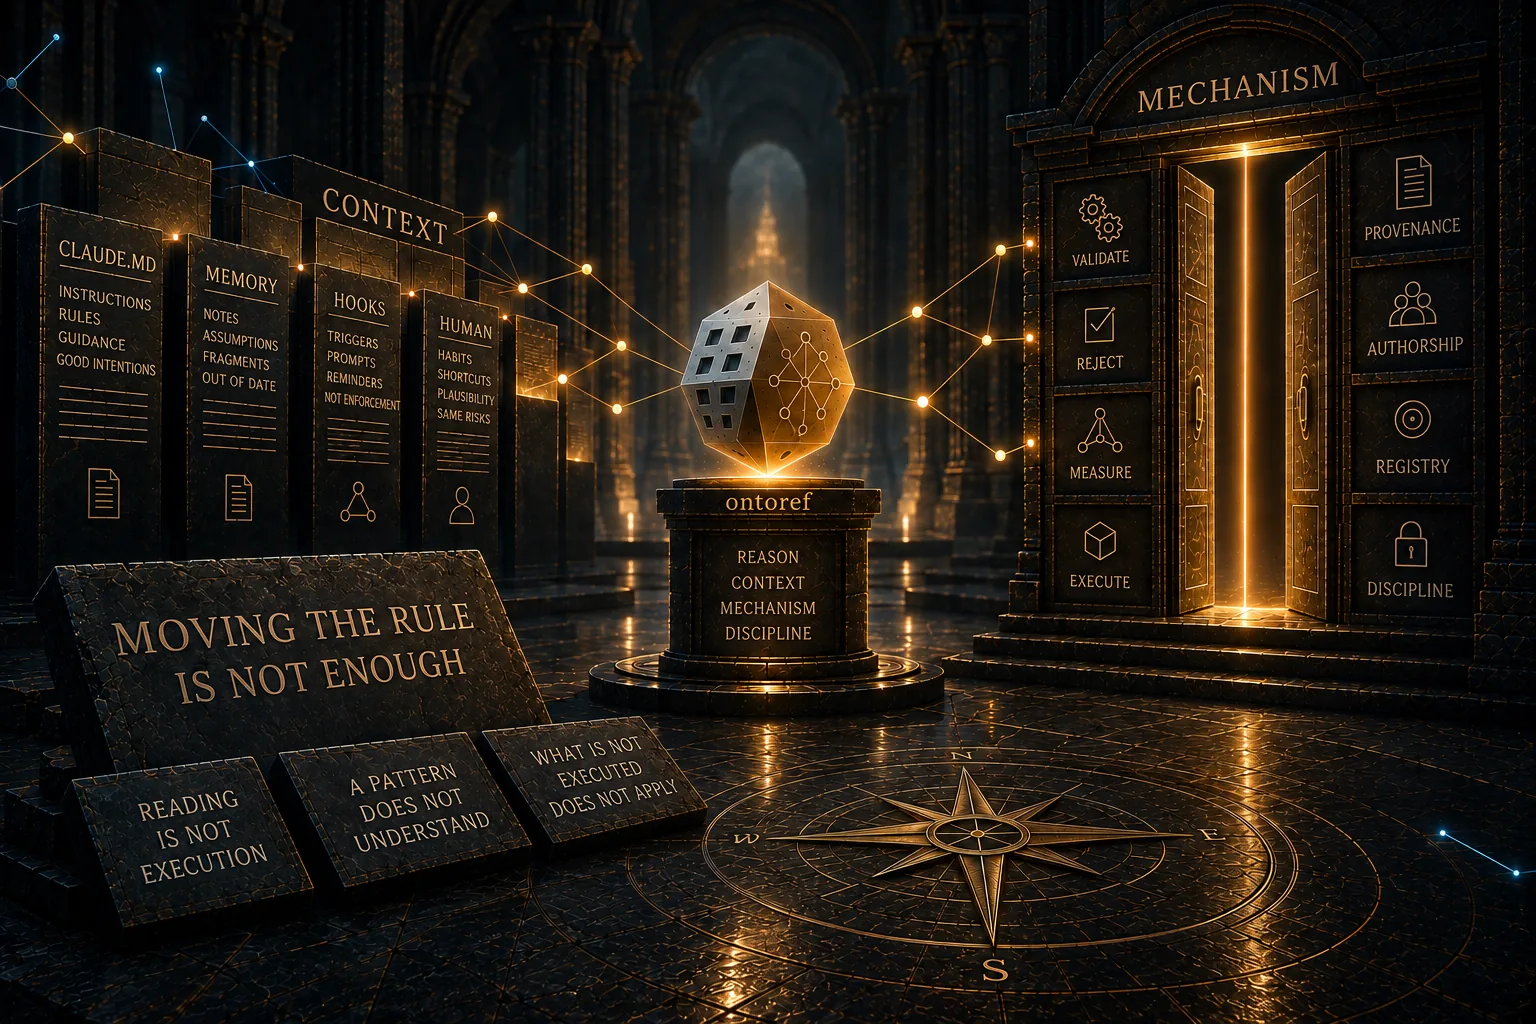
Moving the rule is not enough
A rule written in CLAUDE.md reaches every session in full, and an agent still cited, in an ADR, a session file that did not exist. The fix moved the rule into the command. Measured afterwards, the command flagged mentions that were not citations, let through citations that did not carry the string, and no hook ran it. What makes a rule hold, and why it matters even more inside an authored work.
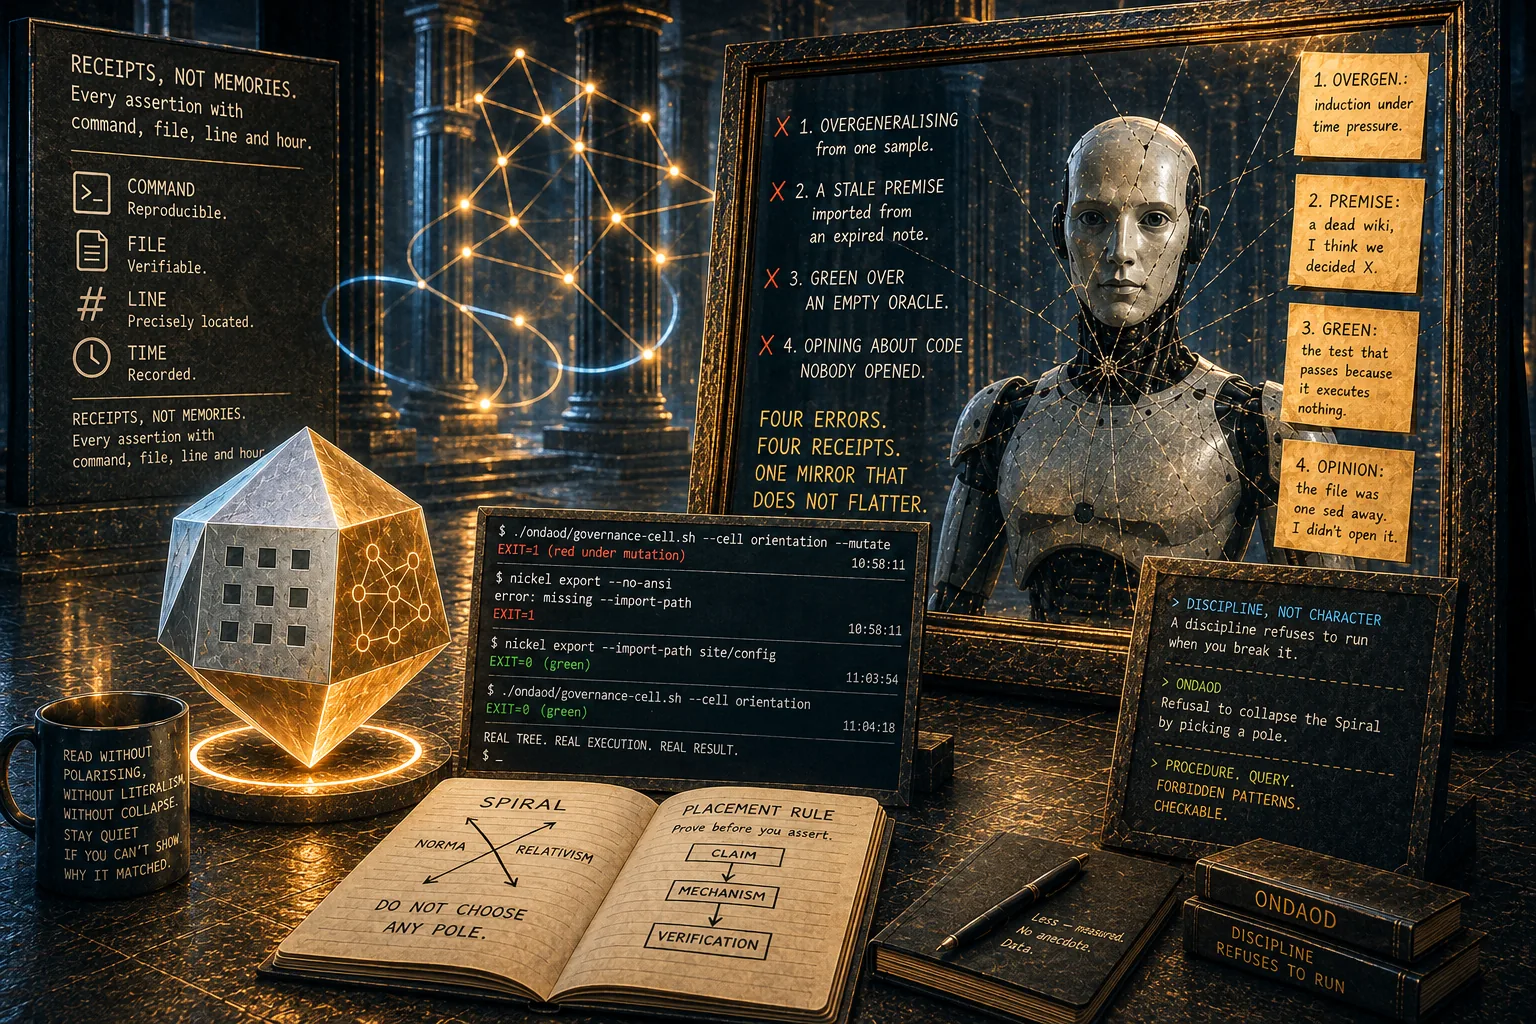
The mirror that does not flatter
It generalised from one example. It quoted a note instead of opening the file it pointed at. It called a check green when it had run nothing. It argued for three messages about a file it had not read. The someone was an AI agent, and the behaviours we file under «AI failure» turn out to be the oldest habits in any working life — only here they leave a trace anyone can re-run. Which leads somewhere less comfortable than a debate about machines: the standard you set for an agent is the standard you actually believe, said out loud, in a place where it gets enforced.
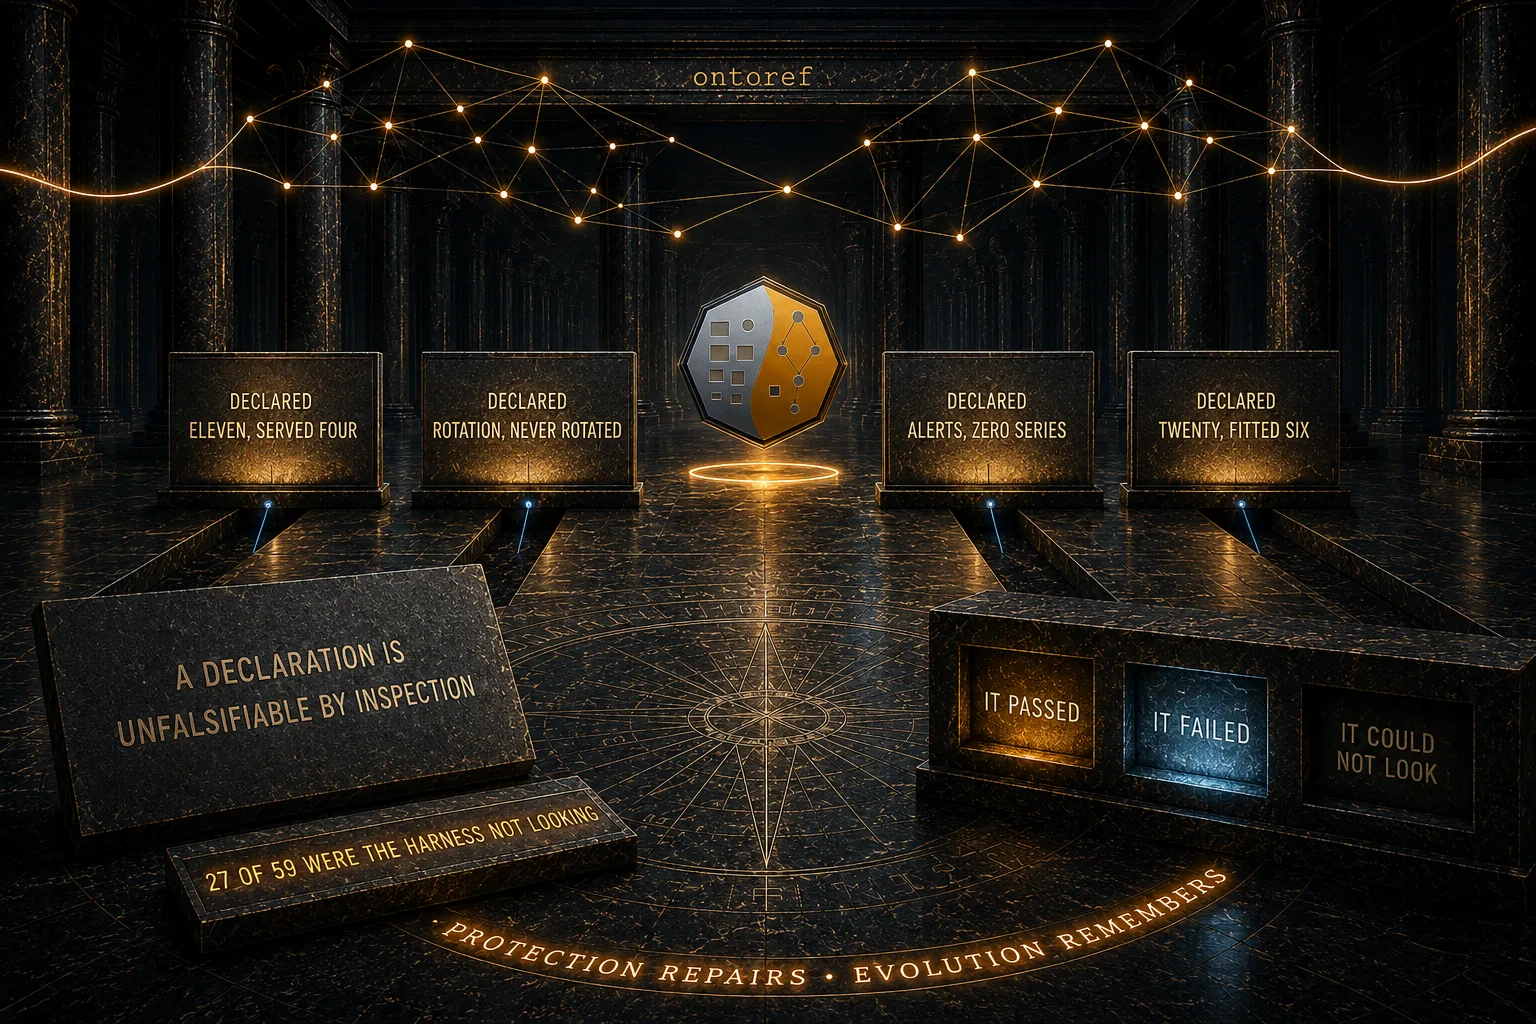
From a compromised WordPress to an operational ontology
Four unrelated mechanisms were found declaring something they did not deliver — an access policy, a credential rotation, two alerts, a worker pool. None of them had failed, because nothing had ever contrasted the declaration against the running system. This post follows what came out of that: a model derived from an incident, three corrections made by the person with the operational knowledge, and a protocol decision that a check must declare what it needs in order to answer at all.
The gap was there before the agent
When an agent invents what a column means, the reflex is to blame the model. Jessica Talisman's argument is sharper: the underspecification was always there, and human inquiry at read time was concealing it — the analyst asked the engineer, got the answer, wrote nothing down, and the cost recurred without ever being attributed to the definition. A machine consumer has no such recourse, so it completes the definition from statistical exposure to thousands of other organizations' schemas. We took ISO 11179-4 and the Z39.19 warrant triad and pointed them at ontoref's own glossary. Of its thirty-odd terms, 11 declare external warrant with no corpus reference and 18 state no boundary at all. The finding is not that we lack the fields — we have them. It is that a default was making a claim nobody had made.
Babel does not need a translator. It needs a witness.
Nicolas Figay argues that AI generates representations, not shared conceptualizations — and that as semantic artifacts get cheap, the bottleneck moves from building ontologies to agreeing about them. Every step of that holds here. What it leaves open is how plurality is supposed to work in practice, and that is a mechanism question: how does one subject verify another's claim without adopting its model? The answer is not a common vocabulary. It is a signed slice. And the same essay caught us doing the thing it warns about, in our own provisioning surface.
A graph that cannot say no
July 2026 filled the conversation with typed graphs for agents, on a thesis that is correct — an untyped edge carries one bit; a typed one carries meaning — and with independent benchmarks that back it. But those same benchmarks say something their popularisers do not finish: one system collapsed to 6.6 average F1 against 59.8 the moment somebody other than its authors evaluated it, and a five-hop chain at 85% per-hop accuracy is worth 44%. The problem is not missing structure. It is that structure, alone, obliges nothing. And the gap the article itself declares empty — a linter for typed edges — has been running here for a while.
The three chairs
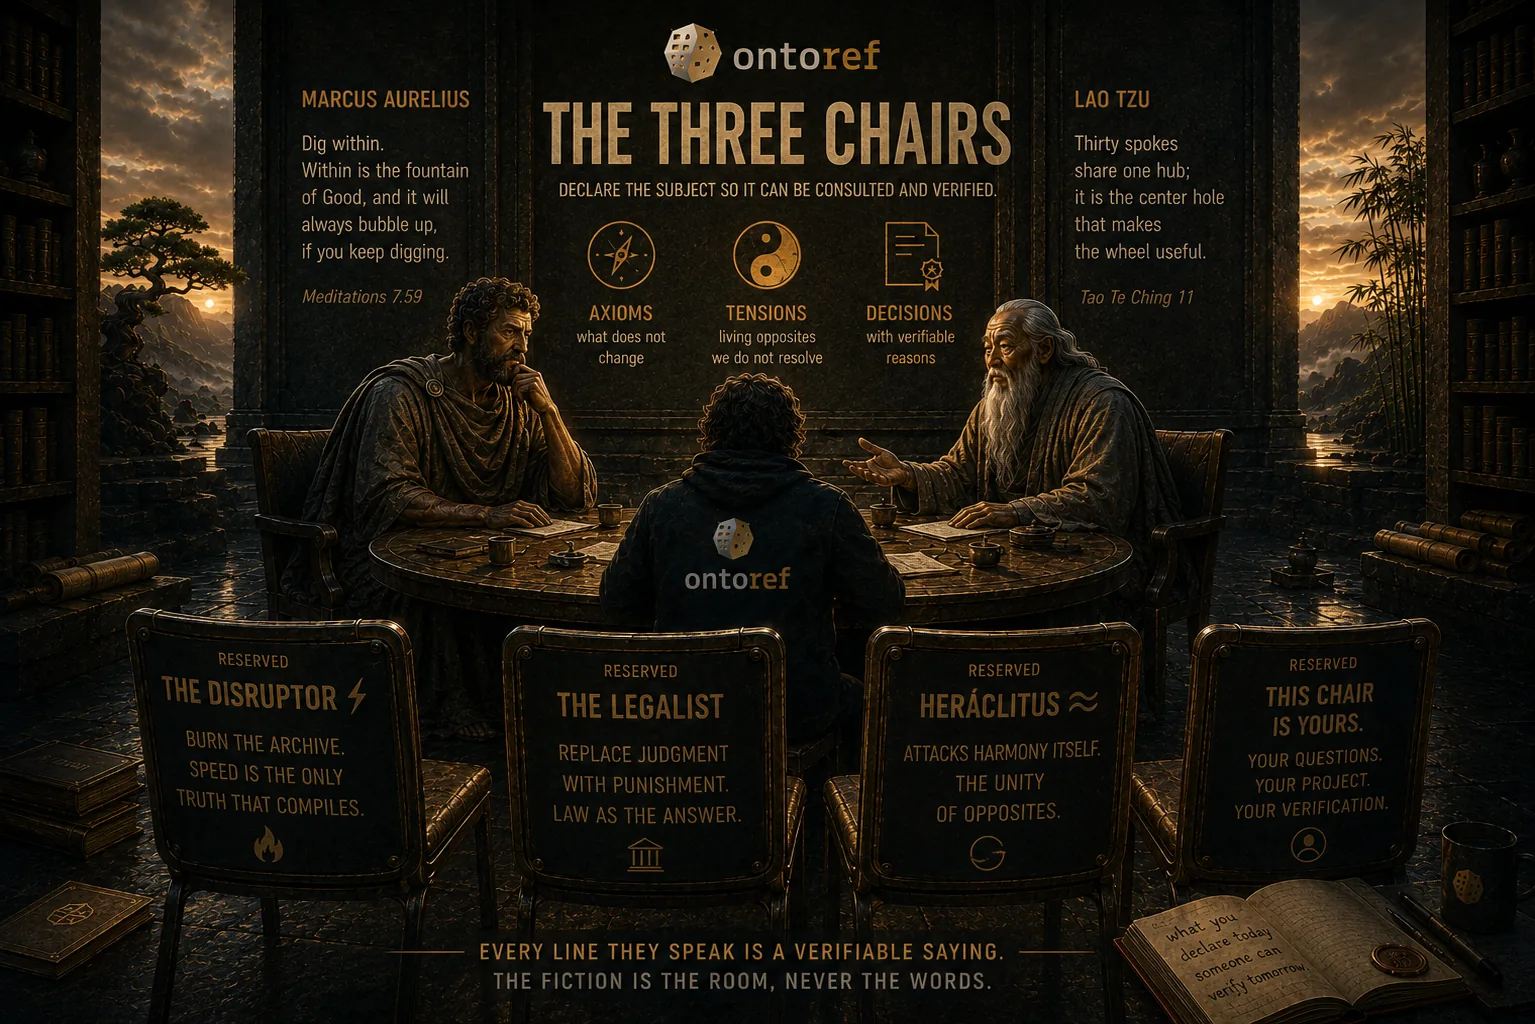
Why would a project pause to declare its axioms, keep its tensions deliberately unresolved, and make every decision carry signed reasons — now, in a time of machines that write faster than anyone can read? Instead of arguing it, this piece stages it: an unnamed maintainer asks, Marcus Aurelius and Lao Tzu answer only with their own attested words, and the skeptics are not straw men in the prose but guests in the room. The Disruptor demands speed, the Legalist demands law, and Heraclitus — the master of the unity of opposites — attacks the serenity of the evening itself. Two objections get answered by the guests. The third is answered by the structure of the interview. The session adjourns with no verdict, tensions open, and one empty chair reserved for the reader.
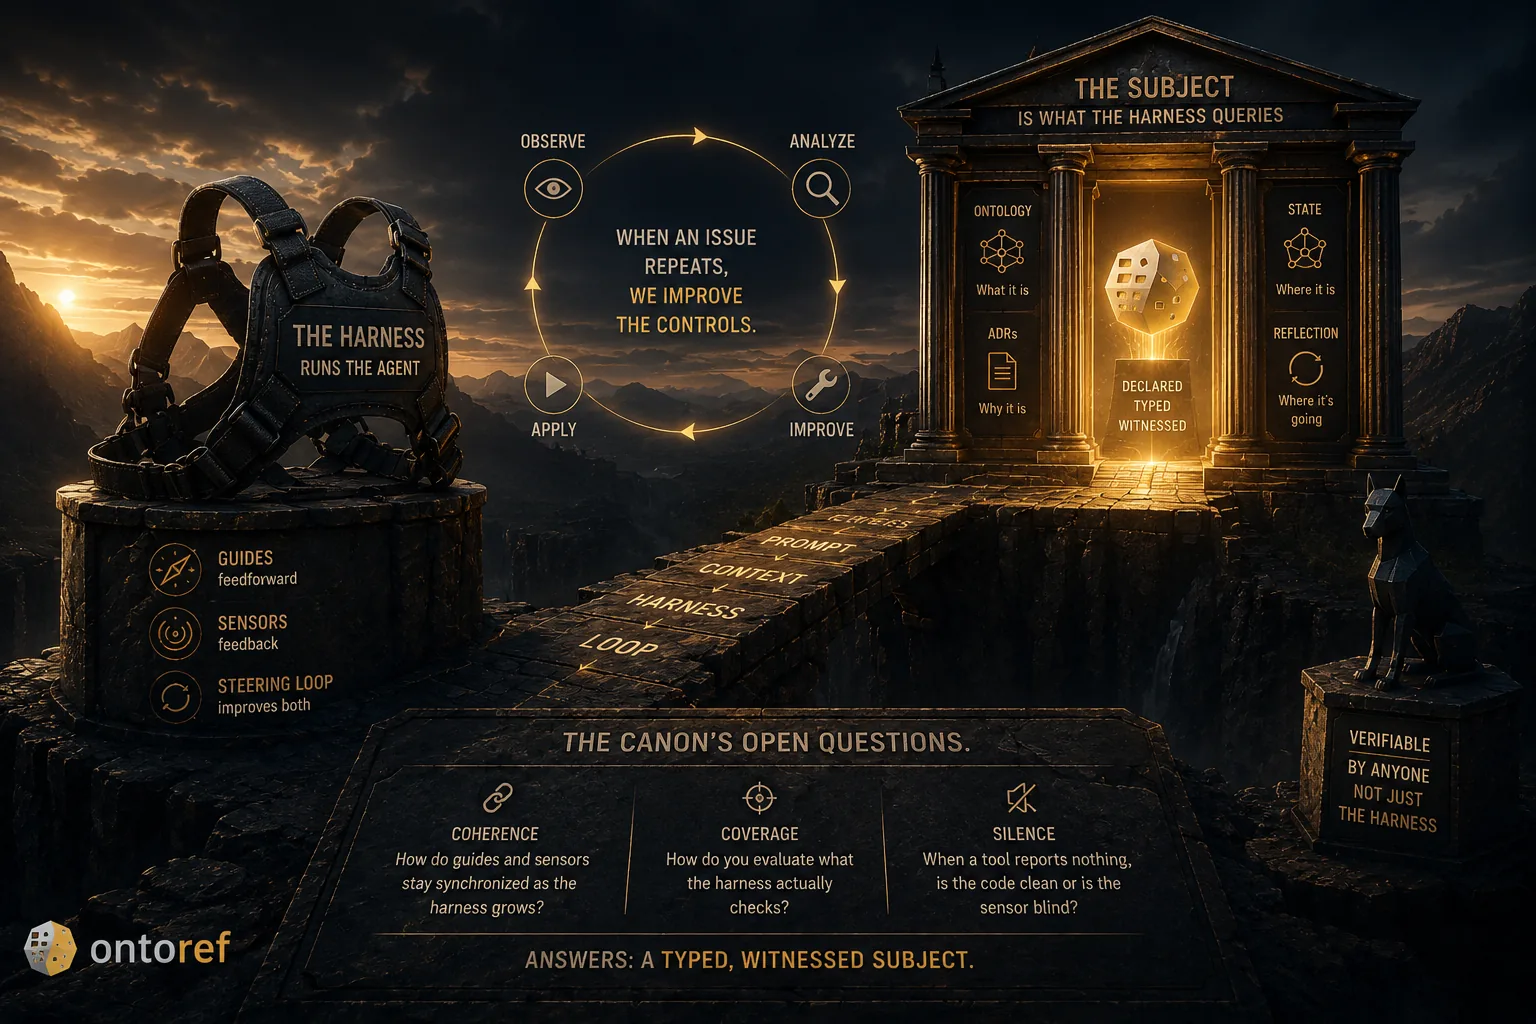
The harness has its canon. Its open questions have answers.
The harness discipline now has a canonical text: guides steer the agent before it writes, sensors correct it after, and a steering loop improves both when issues repeat. This post adopts that vocabulary and takes the next step: the canon's own open questions — how do guides and sensors stay coherent as the harness grows, how do you evaluate harness coverage, what does a silent tool mean — are exactly the questions a typed, witnessed subject answers. A check that does not declare what it looked at is a harness lying by omission; a sensor whose verdict is signed is one you can audit. The harness runs the agent. The subject is what the harness queries.
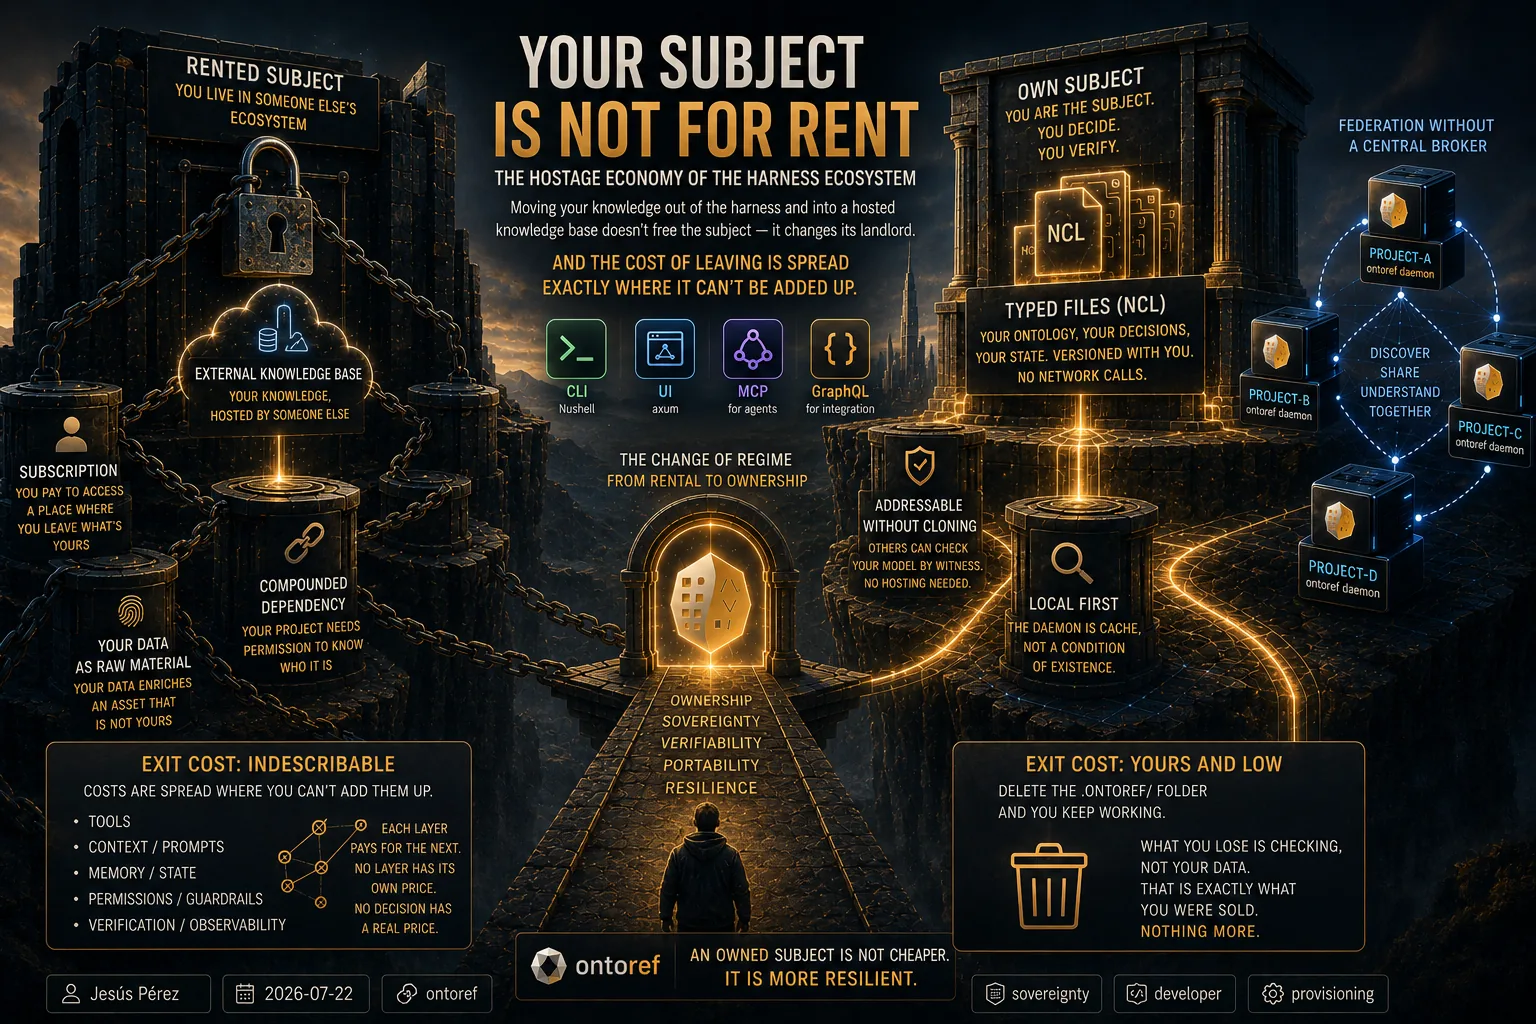
Your subject is not for rent
The harness post left a question open: if your project's knowledge lives inside the harness profile, switching harnesses means losing it. The market's answer — move it out to an external knowledge base — solves one coupling by introducing another. This post walks the harness layer by layer through the pairings nobody decides and everybody assumes, and proposes the change of regime: from renting to owning. No villain: every step of the enclosure is reasonable on its own, and that is exactly the problem.
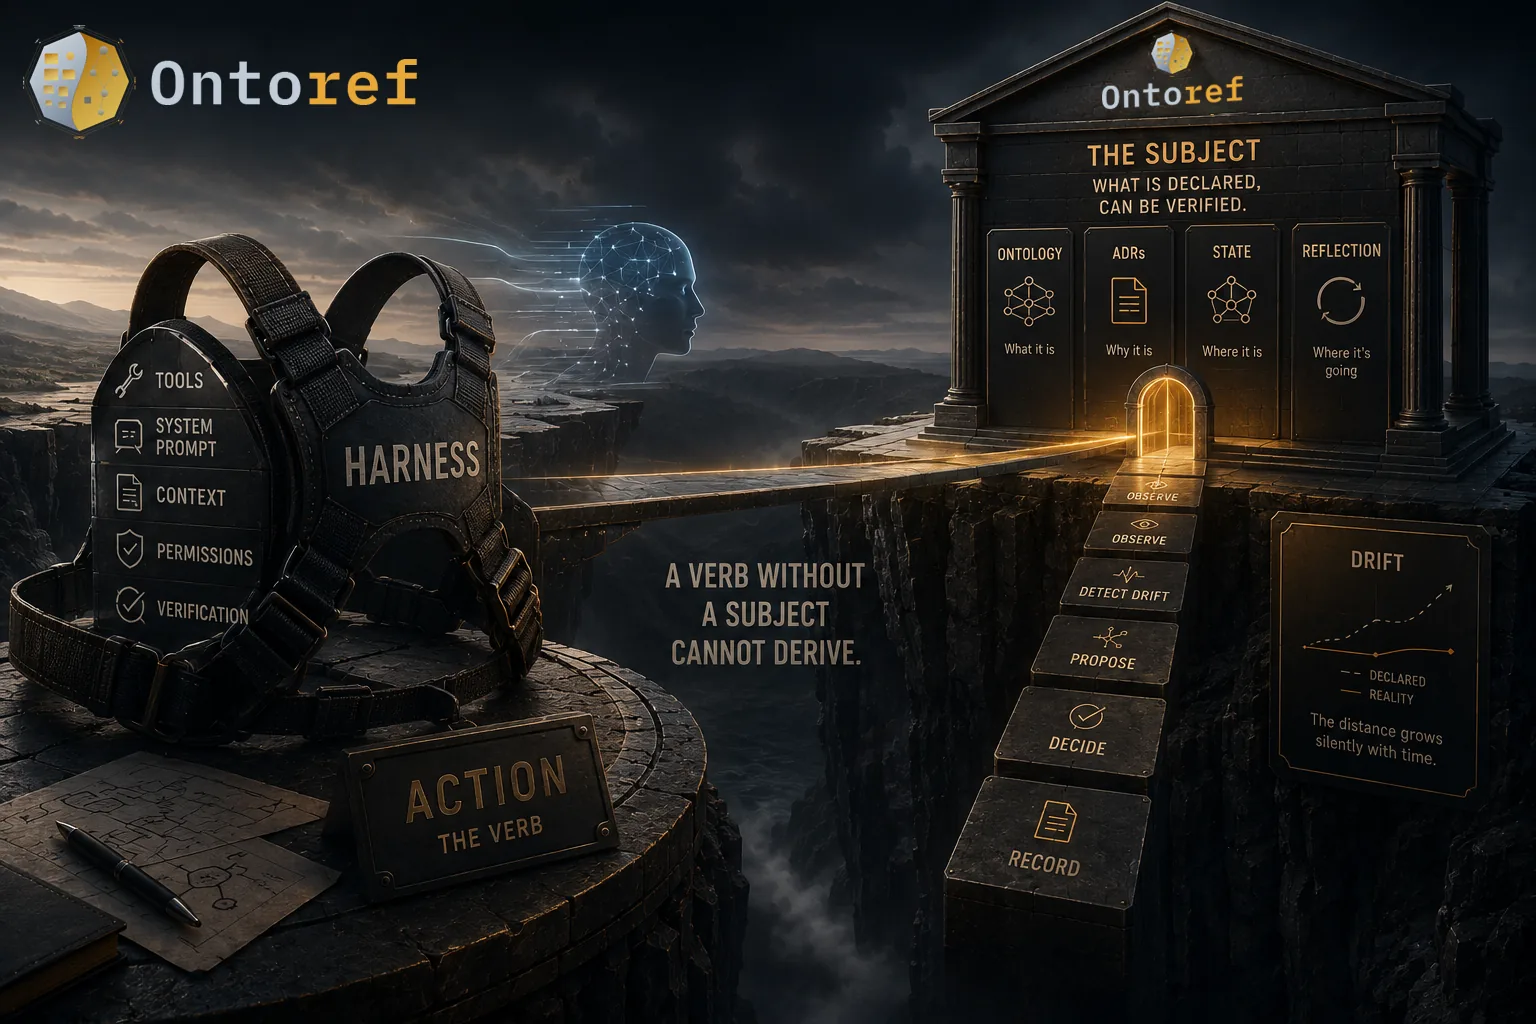
A harness without a subject: what harness engineering doesn't name yet
Harness engineering just named itself as a discipline: documentation as code, architectural constraints, layered verification, periodic consistency audits. All four pillars exist — in flat markdown, held up by manual discipline. This post concedes the whole argument (“the model is commodity, the harness is the advantage”) and adds the next step: the harness governs the verb — how a change is made — and names no subject to check it against. A verb without a subject cannot drift, because drift is precisely a subject diverging from its own declared self.
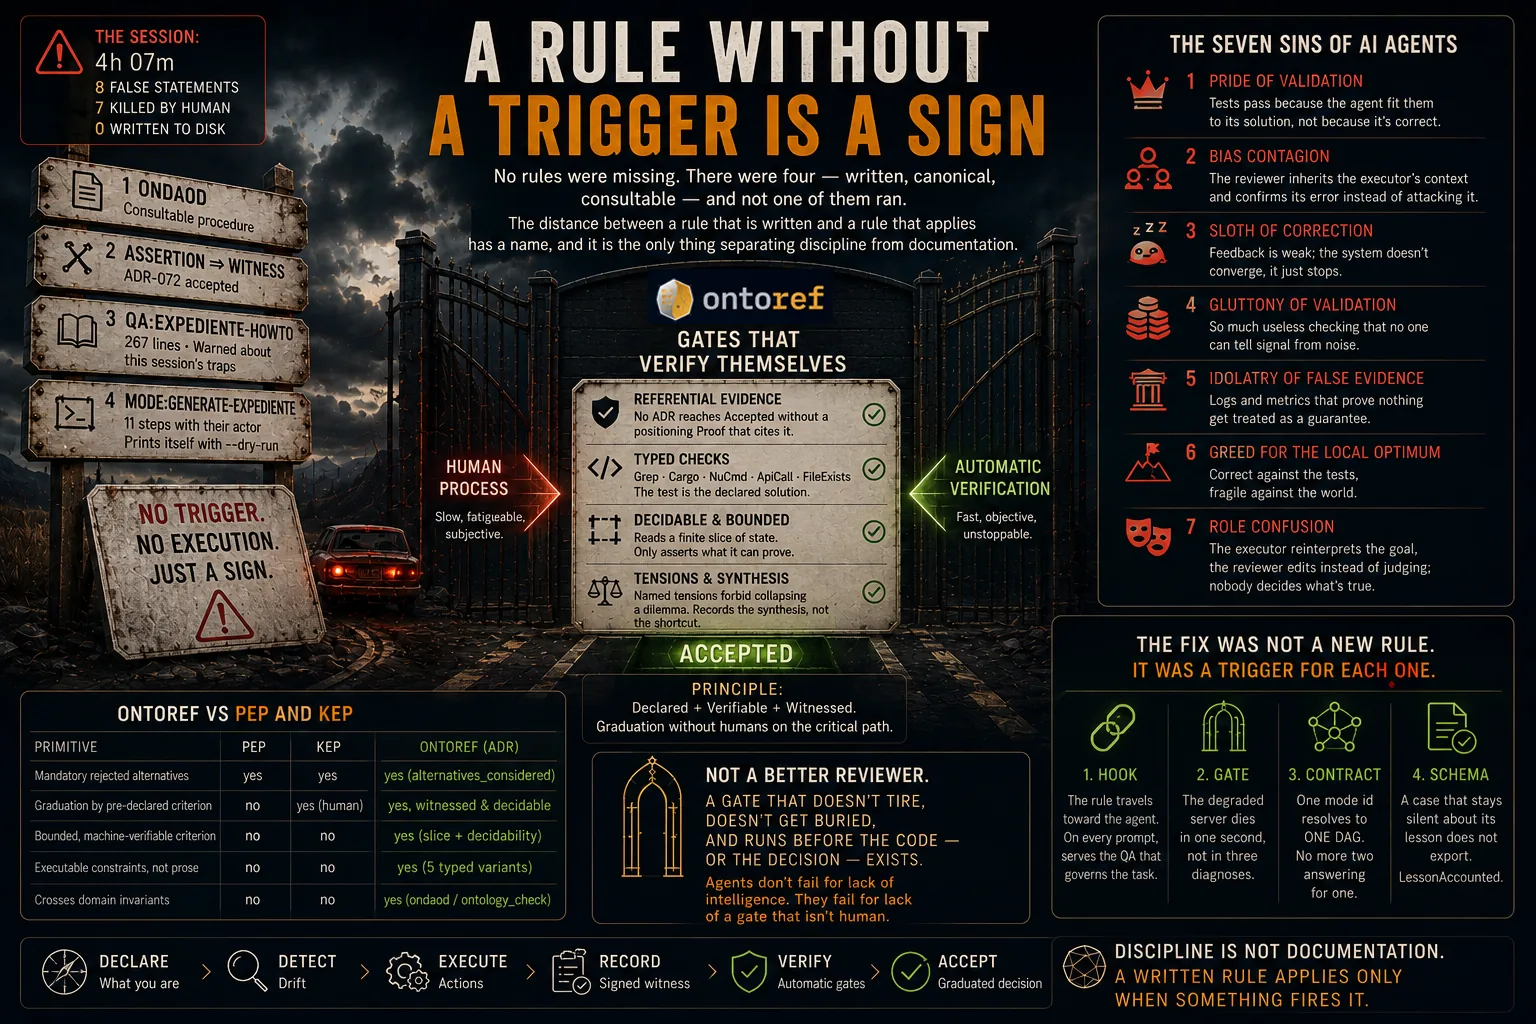
A rule without a trigger is a sign
No rules were missing. There were four — written, canonical, consultable — and not one of them ran. The distance between a rule that is written and a rule that applies has a name, and it is the only thing separating discipline from documentation.