Babel does not need a translator. It needs a witness.
An essay doing the rounds separates representation from meaning and ends by asking us to learn to inhabit Babel. It is right, and it stops at the mechanism. Ours is not convergence: it is verifying a slice of somebody else's model without adopting it.
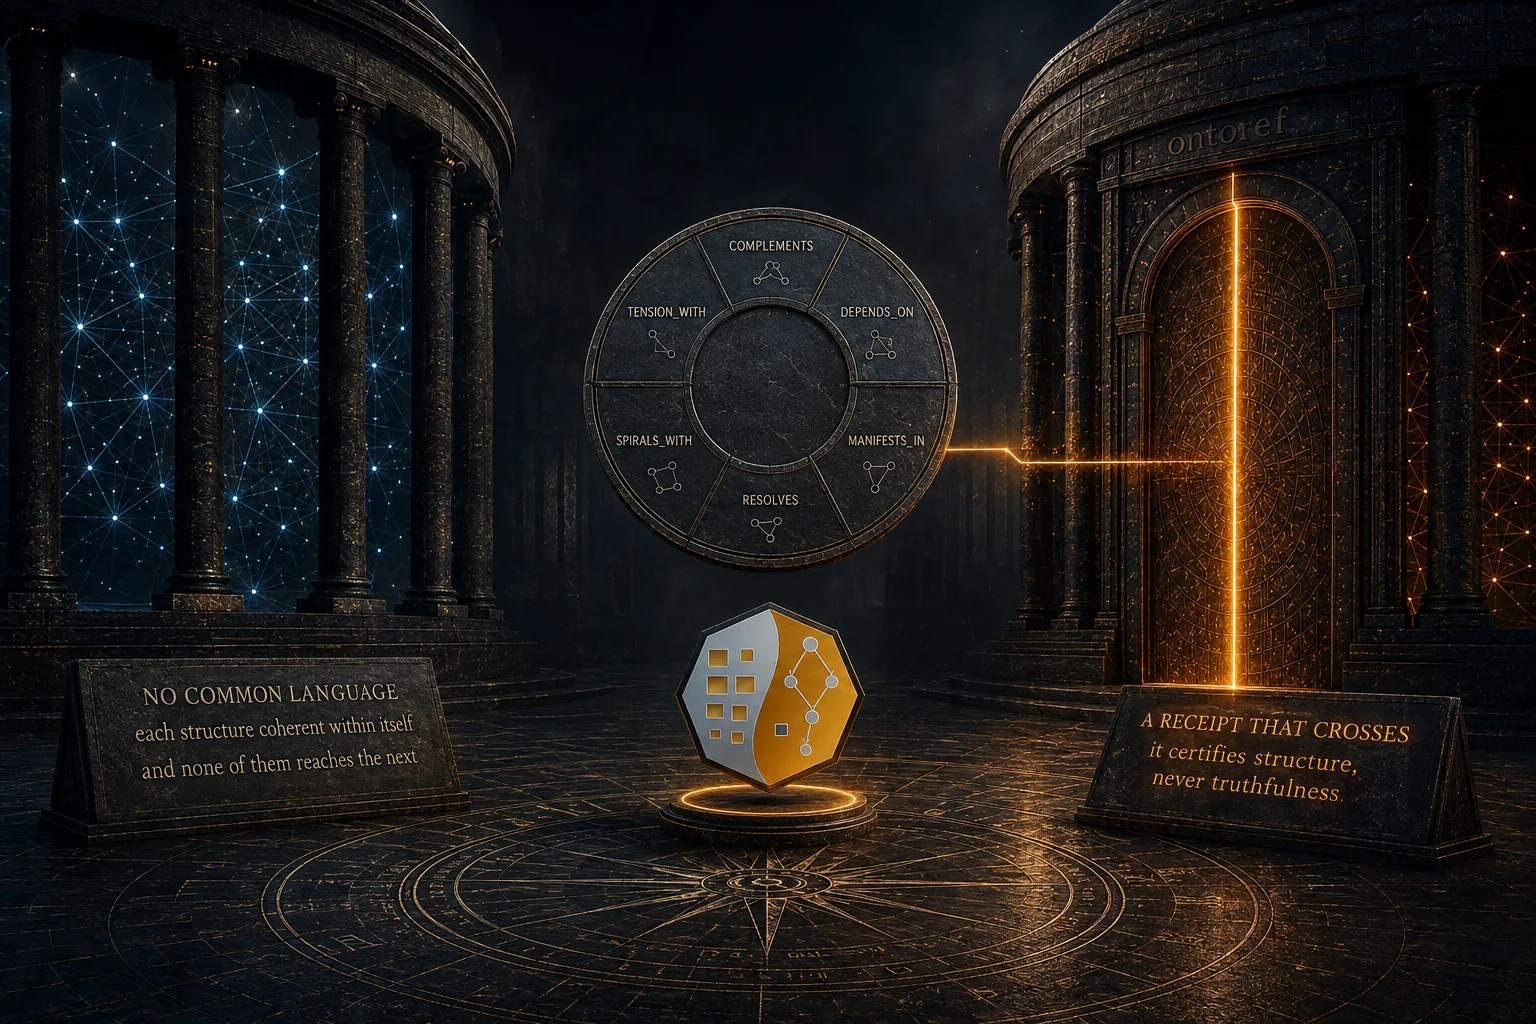
Babel does not need a translator. It needs a witness.
Nicolas Figay published The Ontology Illusion: When Representation Is Mistaken for Meaning, and it makes an argument worth reading slowly. Its thesis, compressed: LLMs and graph platforms now generate semantic artifacts at nearly zero cost, those artifacts are not ontologies in the sense ontology engineering spent decades refining — a conceptualization shared across communities — and treating the resemblance as the thing produces a new illusion, that interoperability has become an engineering problem AI has solved.
He is careful about his own text, which is more than most such essays manage. His closing note calls it «deliberately provocative and rhetorical», says it stages a premise he keeps encountering rather than defending it as settled, and admits it sits in tension with his own position — pointing at The Other Ceiling and Beyond Explainable AI as the fuller grounding. Read alone, the essay would have him defending classical ontology engineering as a stable baseline, and he does not: he says its ceiling was there first and never made it into the marketing. The second of those two is titled Beyond Explainable AI: From Symbol Processing to Semantics in a World of Babel — the Babel in the headline above is his before it is ours, and this post’s title is a reply to that piece as much as to the essay. So this is not a rebuttal, and it is not a reading of one piece. Most of it is simply true here, and one part of it landed on this project as a correction.
Where there is nothing to argue
His section 8 says meaning is not generated: it does not emerge from data, is not extracted from text, is not computed by a model. It emerges through interpretation, negotiation, practice, institutionalization.
That is, almost word for word, an axiom this protocol has been built on — except stated as a mechanism rather than as an observation. ADR-056 puts it this way: knowledge is accredited, not deduced or generated; deduced or generated output — including an AI agent’s — is not usable knowledge until it is signed. A model’s output does not enter the verifiable set by being plausible. It enters by being attested, and the attestation is checkable by somebody who was not there.
Beyond Explainable AI arrives at the same floor down a different road — from philosophy of representation rather than from agent hallucination. «The machine never manipulates “meaning” in the human sense», he writes there: an OWL reasoner and a transformer are, formally, doing the same kind of thing with symbols, and the distortion lives in the chain from reality to interpretation rather than in the machine’s honesty. Two independent arrivals at one place, which is the only reason the agreement is worth anything — neither is a datum the other can cite as proof.
The difference between his sentence and that one is not the claim. It is that a sentence in an essay is advice, and a validator that refuses unsigned state is a floor. Both are the same idea; only one of them is load-bearing at four in the morning when an agent is confident and wrong.
His section 5 lands equally cleanly. «80% correct» is a misleading metric because the missing 20% is not randomly distributed noise: it contains precisely the distinctions that matter for coordination. The chapter of this project’s own book that covers the same ground puts it as every model is a chosen loss — maturity is not the complete map, it is knowing what you sacrificed when you chose this one.
The Other Ceiling reaches that from formal logic instead of from epistemics, and it adds the part the chapter does not have: the loss was a design decision, taken deliberately, with a name. «Description logics were designed for a reason: to trade expressivity for decidability.» So OWL DL was never built to carry a domain’s full complexity — only the fragment of it that stays decidable — and «practitioners learned to model around the ceiling rather than into it». That is what makes the essay’s argument something other than a complaint about AI: the ceiling it describes is not new, and the discipline it is measured against had its own, first, and rarely put it in the brochure.
The word is a homograph, and we had never said so
Here is what the essay actually cost us, which is the only part of this post that is news rather than agreement.
In the tradition the essay describes — ontology engineering, the semantic web — an ontology is an artifact whose whole value is agreement between communities. In this protocol, an ontology is the declared subject of one project — its axioms, its tensions, its state — whose whole value is being refutable against that one project. Both senses are legitimate and they are not the same thing. A reader arriving from the semantic-web world and running ontoref describe project is expecting a shared controlled vocabulary, and will find a system’s model of itself.
Neither of the two registries that govern vocabulary here said so. The lexicon governs how the word is rendered between languages and carries the one-sentence gloss for a reader who has met «ontology» at best in a philosophy class; it deliberately holds no definition and points at the glossary. The glossary defined the ontology/reflection pair structurally — which files it is — and never disciplinarily. The distinction fell exactly between two entries that each correctly pointed at the other.
It is now declared, in the protocol seed rather than in this project’s own glossary, because the confusion is not a fact about us: every project that adopts the protocol and creates an .ontoref/ontology/ inherits the same homograph. Along with it, two forbidden readings — that a project’s ontology is a conceptualization shared between organizations, and that ontoref is an answer to semantic interoperability between them. It makes one subject falsifiable. Agreement between subjects is not something it produces, and saying otherwise would sell a thing that does not exist.
The mechanism the essay leaves open
Figay’s conclusion is that the goal is no longer to enforce a single ontology but to make differences «visible, navigable, and negotiable» — semantic cartography, and learning to inhabit Babel rather than escape it.
Agreed, and the whole question is how. «Negotiable» describes an outcome, not a mechanism; every organization that has ever run a semantic alignment programme wanted differences to be negotiable too, and got a committee.
The mechanism here is called witness-not-clone (ADR-028), and it is deliberately smaller than agreement. One subject verifies a slice of another’s declaration — this claim, this check, this input, this instant — without adopting its model, without cloning it, and without either party converging on a shared vocabulary. The verification is a signed receipt: it proves a check ran and what it returned. It does not prove either model is right about the world, and ADR-050 says so in writing — a witness certifies structure, never truthfulness.
There is an objection to that, and it is his. In Beyond Explainable AI he writes that «trust rarely originates from the artifact itself. It originates from the socio-technical process that produced it» — a formula is trusted for peer review and empirical validation, a standard for the boards that examined it; the document is merely a carrier. A signed witness is an artifact, so the objection lands squarely on the mechanism, and the answer is not to deny it. The receipt is not the source of the trust. It is the checkable transport of a process’s verdict — and what ADR-050 renounces is precisely the thing the objection warns about: the receipt never claims the process was right, only that it ran, on this input, at this instant, and returned this. Lift it out of those coordinates and it means nothing. That is a much smaller claim than trust, and it is the only one an artifact can honestly carry on its own. It is also not a hypothetical safeguard: a witness here once certified a world that no longer existed — a perfectly valid receipt, of a check that had really run, against a state that had since moved. Honest and useless at the same time, which is exactly the size of the claim a receipt makes.
That renunciation is what makes plurality workable rather than merely tolerated. If verification required understanding the whole, then two subjects could only relate by one absorbing the other’s model, which is convergence wearing a friendlier name. Because verification is local and partial by law — the protocol forbids any gate that demands complete knowledge as a precondition for a valid act — two models that disagree everywhere can still exchange one checkable claim. Babel does not need a common language. It needs receipts that survive the crossing.
What this is not
It would be easy, and dishonest, to present that as an answer to Figay’s problem. It is not.
His problem is agreement between organizations about what a customer is, who owns the meaning of revenue, which perspective wins under regulation. That is governance among people, and no protocol produces it. What is on offer here is narrower and does not want to be mistaken for it: a way for one subject to state what it is precisely enough to be caught being wrong, and a way for a second subject to check one of those statements without swallowing the first one whole.
If you came looking for the thing that makes five departments agree, this is not it, and the honest move is to say so on the way in rather than after adoption.
The uncomfortable half
His section 4 is the one that came back around. Semantic artifacts have moved from scarcity to abundance: every dataset, every platform, every agent can now produce its own ontology-shaped structure, and the risk is not chaos but proliferation without a threshold. Read that with agent context provisioning in mind and it stops being about ontologies. This project governs who may provide context to an agent and what counts as authoritative (ADR-074), and declared no ceiling on how much — so view mount materialized an entire discipline and describe capabilities emitted its whole inventory, on the surface whose entire job is to keep an agent’s knowledge accredited. The ceiling did exist, as a comment inside a carrier: the session hook recorded that «describe capabilities would be the complete thing and it is 58k tokens: a cure more expensive than the disease», and quietly called three cheaper verbs instead. A correct measurement and a correct decision, in the one place ADR-074 forbids a rule to live. Knowledge that governs, held where nothing can check it, is representation again.
That gap is now floored rather than confessed. The bound is declared per view in the schema and enforced at both entry points; a level the mount cannot retrieve refuses the mount instead of silently shrinking the slice; and describe capabilities returns 1,632 bytes by default against 260,471 for the full inventory, every section named, counted and reachable by its own verb. The ceiling itself was not imported — a cap of «four notes per prompt» is a fact about one vault on one date, and a view with none now reports unmeasured, not unlimited, which is a different claim from silence. What the floor does not cover is the part worth publishing, and the autopsies are in the open rather than summarized here — three of them, all from the same week. The new fail-closed rule, on its first run, was a gate that could not see: it judged retrieval by an exit code, and describe <unknown> exits 0. The validator that reports on this project’s own ontology answered «0 findings» while the axiom asserting that the project describes itself pointed at three files that did not exist. And three separate surfaces reported a record that had never been written, agreeing with each other perfectly, none of them having opened the file — which had not changed in twenty-six days. Three greens, three consistent answers, none of them correct. Which is the five-word version he had already written, in The Other Ceiling: «Consistency is not correctness. Decidability is not adequacy.» A green check accredits consistency, never correctness. That is why the essay was worth the hour — not because it said something the protocol had not declared, but because it named a plane the declaration had not reached; and the honest answer to that is a floor laid where the gap was, plus the discipline to keep measuring what the floor still cannot see.